
“The reasonable man adapts himself to the world: the unreasonable one persists in trying to adapt the world to himself. Therefore all progress depends on the unreasonable man.”
Oxford
AIGO
I’ve spent the past few weeks founding AI for Good Oxford, a community that connects technical machine learning researchers with domain experts working on important problems. This month, we launched the AIGO roundtable, where researchers at the University of Oxford working at this exact intersection are invited to share their work.
In academia (or rather, at least in the Statistics Department), I’ve found that these kinds of contributions tend to run slightly under the radar, as they are not new science per se, but rather applications of known algorithms to existing problems. I personally don’t think this undermines the contribution at all, because a massive amount of testing and many domain-specific considerations are involved when adapting statistical or mathematical algorithms to specific applications. The knowledge gained from selecting and adapting the best algorithm for a given problem can be a novel result in itself.
The space is further limited by academic siloing: those with the skills to solve the most interesting and important problems don’t typically have in-depth knowledge of, or exposure to, the exact kinds of problems they are best suited to solve. Likewise, domain experts have robust knowledge of the nuances of the problems they own, but don’t have the same degree of technical expertise as machine learning specialists. The AIGO roundtable aims to solve this by connecting ML researchers in search of interesting problems with domain experts whose problems could benefit from some sort of machine learning solution.
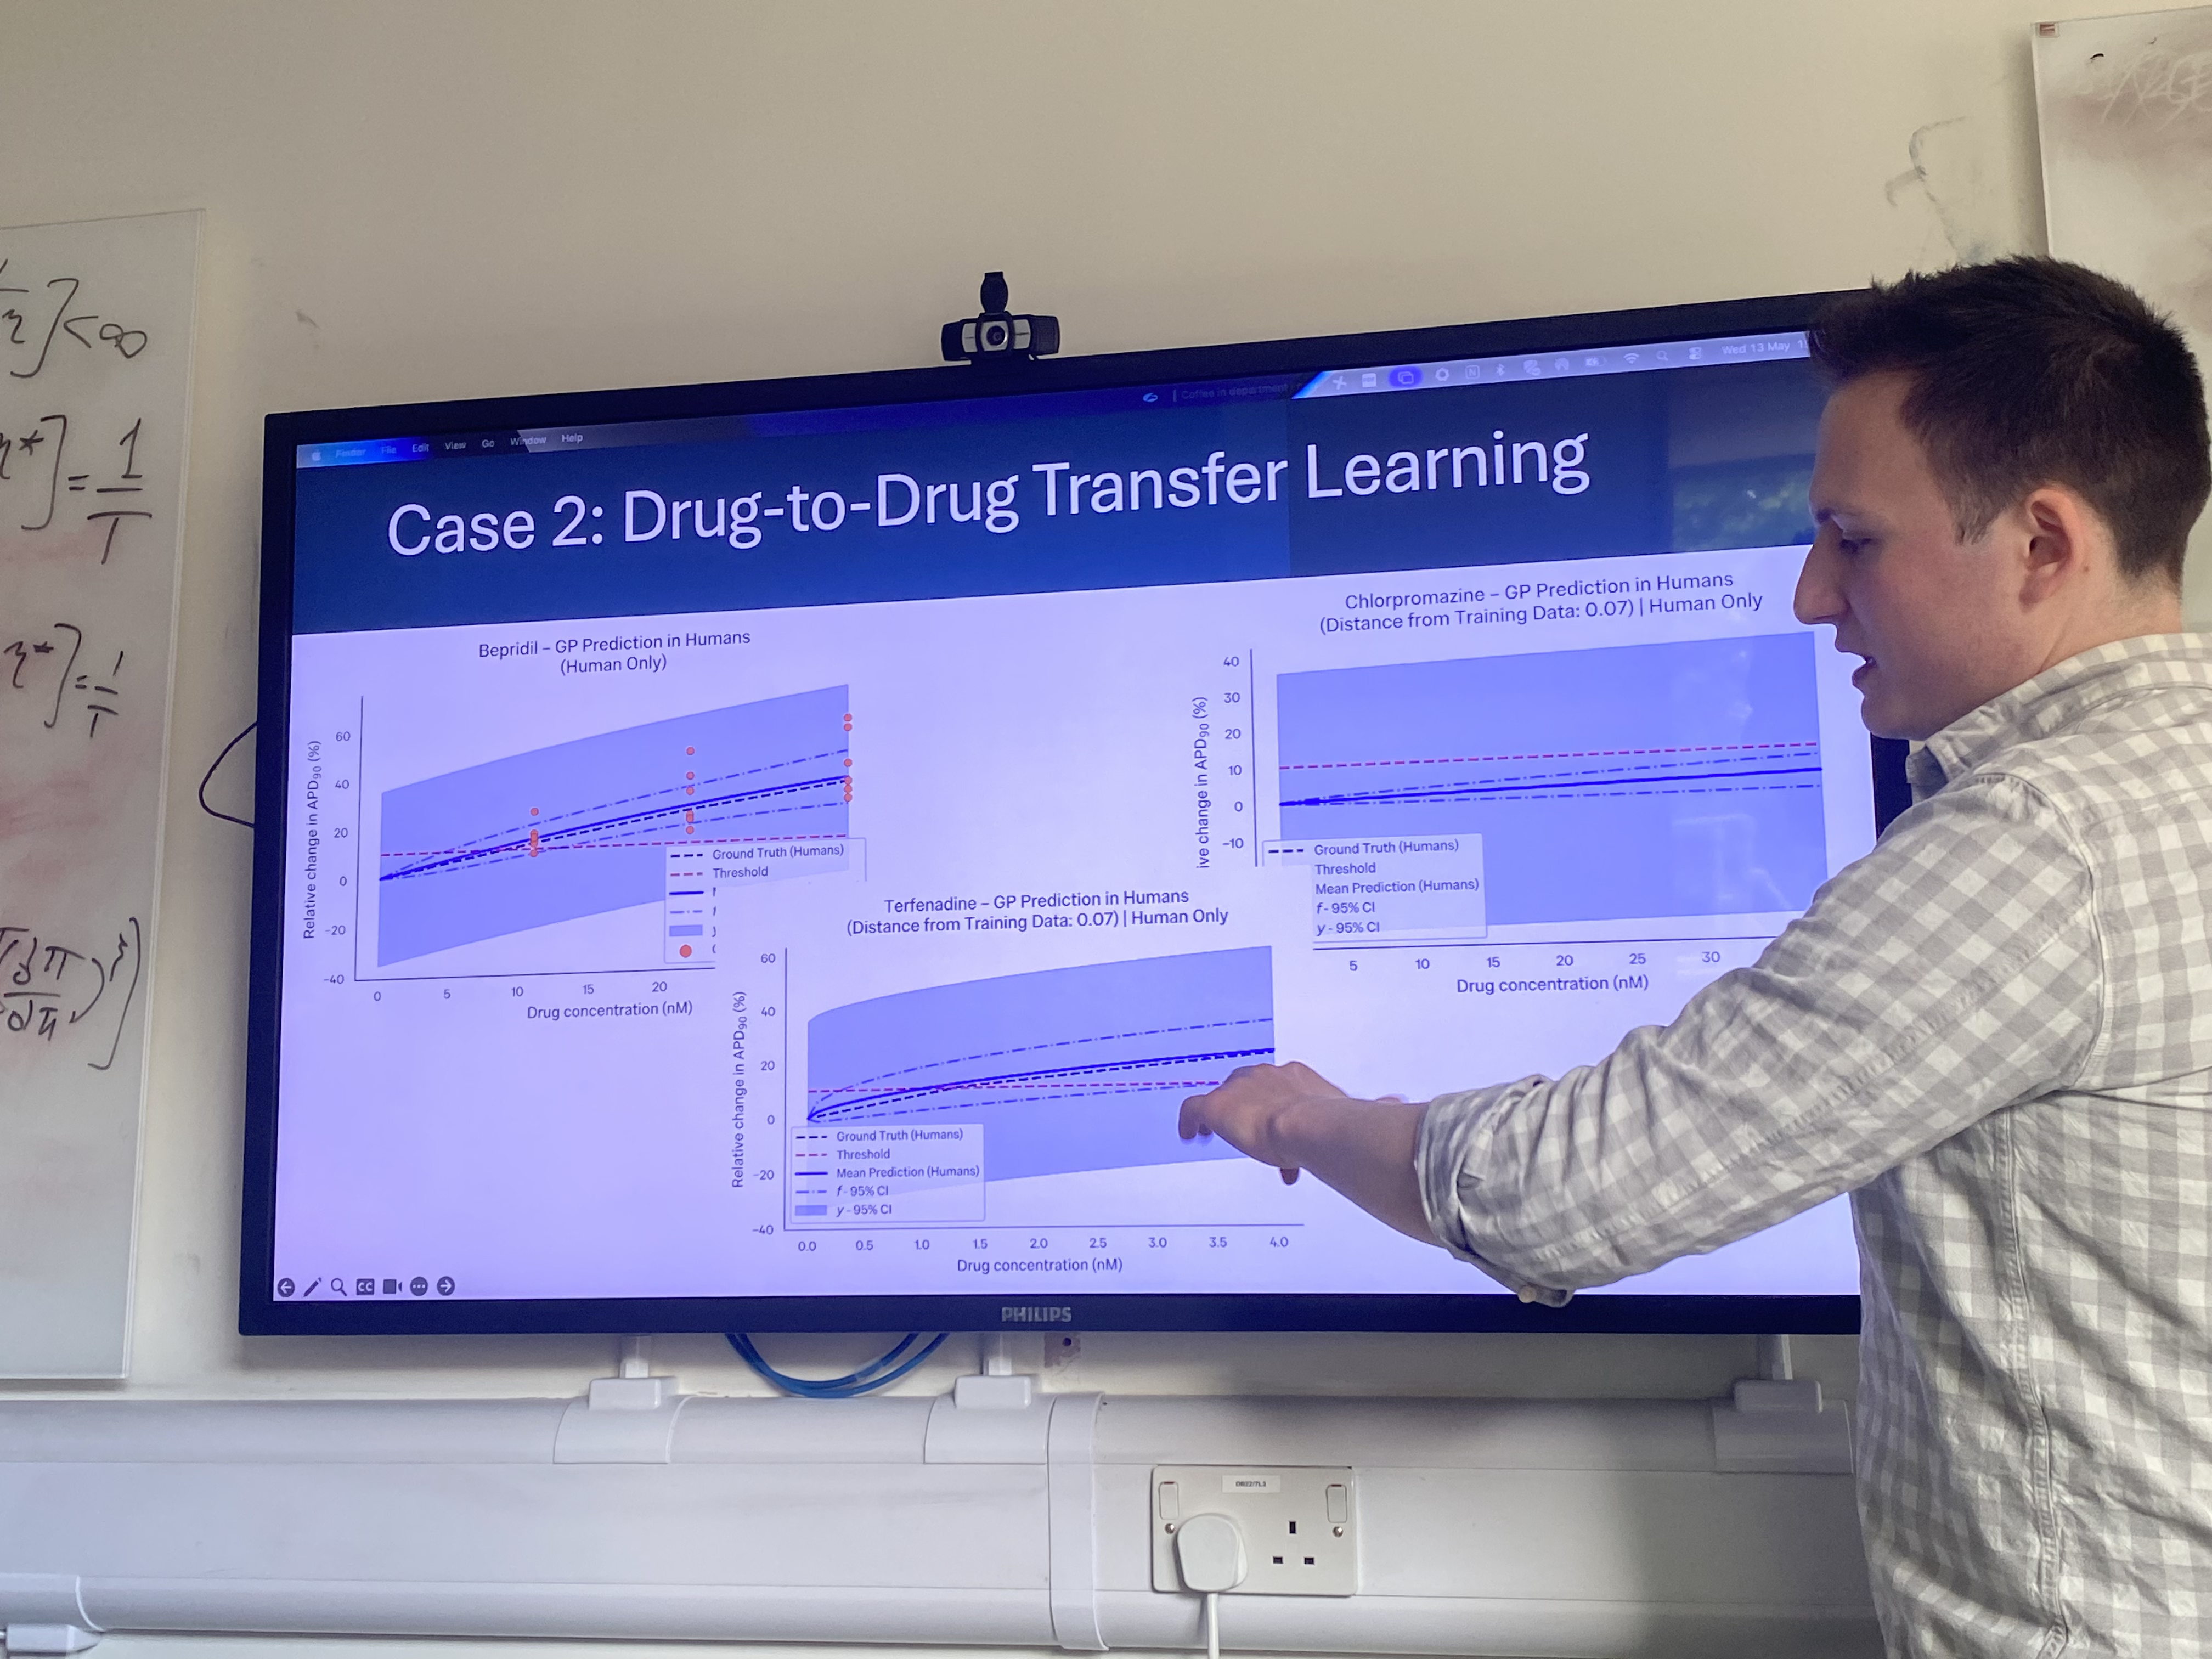 Isaac Hayden, presenting on his work using Gaussian processes to improve translations between animal and human experiments in healthcare.
Getting this up and running was a particularly good lesson in delegation, as I was in Vienna for a conference during the first roundtable presentation. Leaning on other people to get things done doesn’t come naturally to me (the biggest worry I had was that no one would show up for the first presentation), but the team I’ve put together for AIGO has really come through (especially Gayeon Ji, who is running the roundtables). I’m really looking forward to hearing from the other speakers.
I have to admit that a huge benefit of doing this is that I can invite any researcher whose work I find interesting and essentially have them give me a small-group presentation on their topic. So, if you’re a graduate student who wants to make cross-disciplinary connections, I definitely recommend starting your own research seminar. People are genuinely very keen to present their work and are almost always very flattered that you’ve found their research interesting. I’ve had a huge success rate with people agreeing to present at AIGO, and this is just a random initiative that I made up!
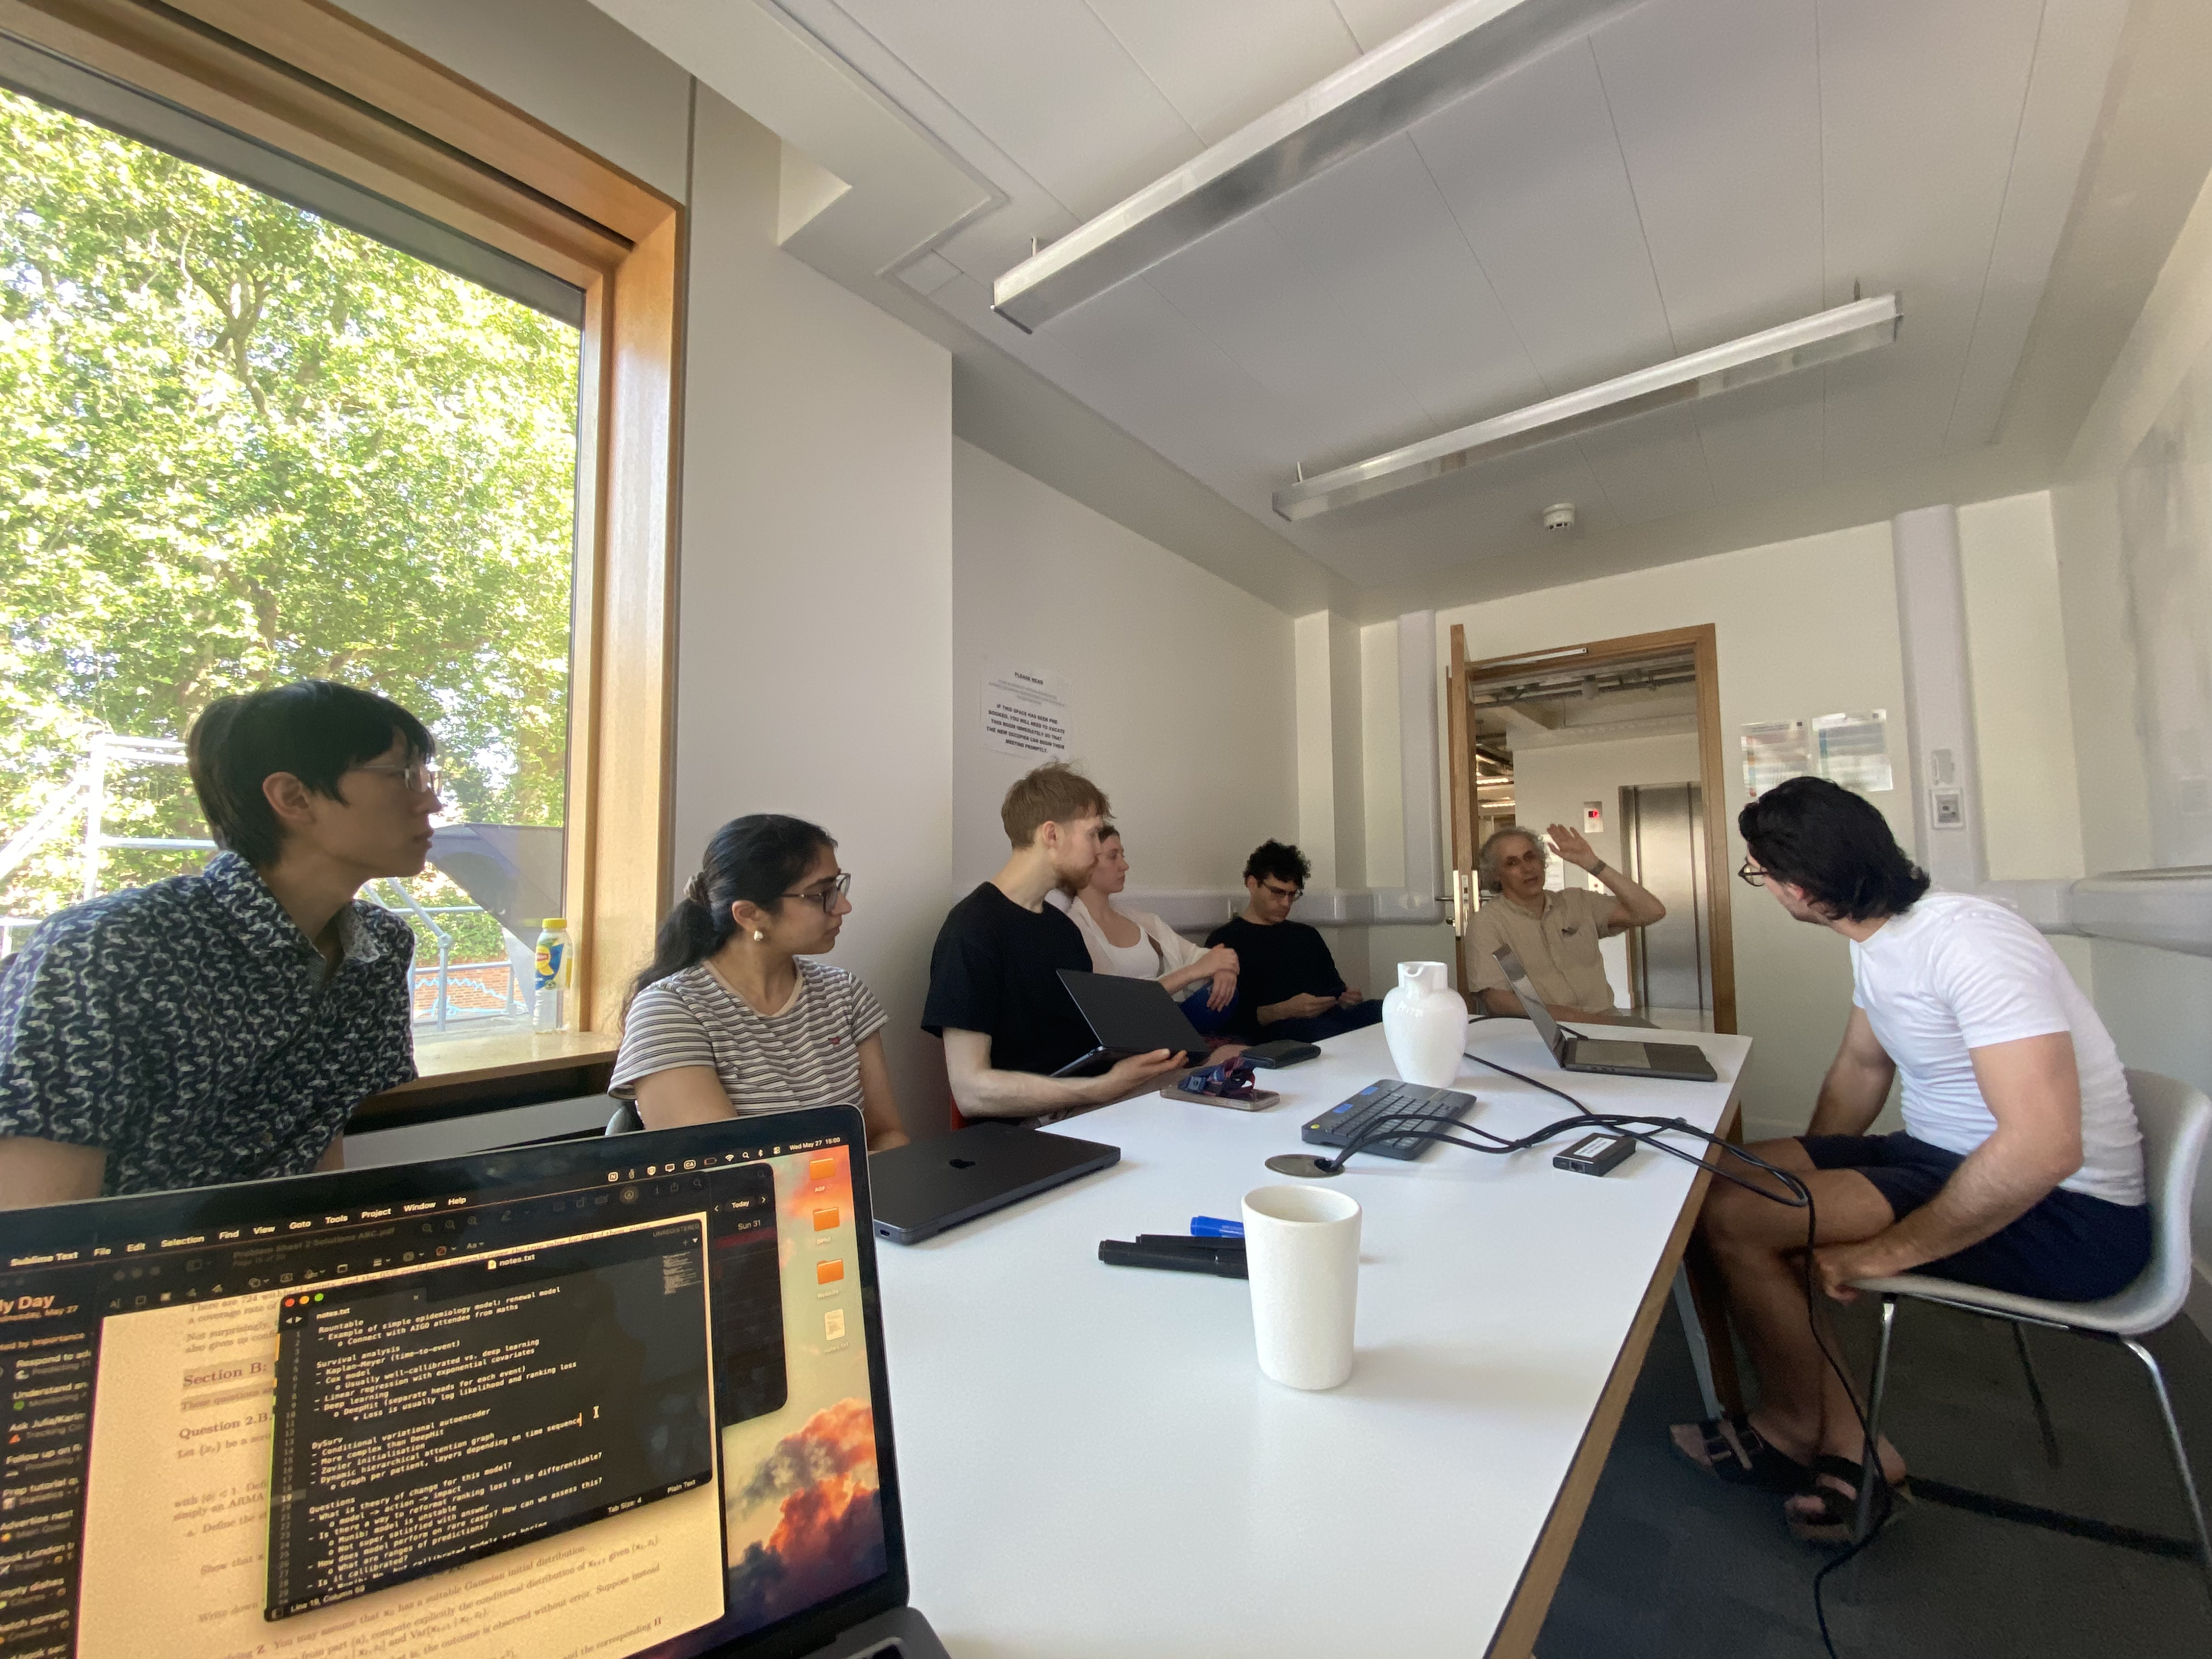 Munib Mesinovic, whose presentation on a method for predicting individual death in a clinical setting using deep learning attracted a diverse audience, from professors, to clinical practitioners, to data scientists.
Oxford City Council Elections
Oxford City Council elections were held on May 7th. As mentioned, I’ve been donating some of my time to helping the Green Party with data strategy (specifically, helping to link respondents from door-to-door surveys with the voter register that the City Council provides, so door-knockers know exactly whom to target when putting up Green Party posters and sending reminders to vote on election day). I also came out to do a little door-knocking myself the week before the election, when there was nothing else left to do on the data side.
All our strategy and knocking seem to have had some impact, as the local Green Party did quite well, securing 13 seats (only 7 fewer than Labour, who had the most seats).
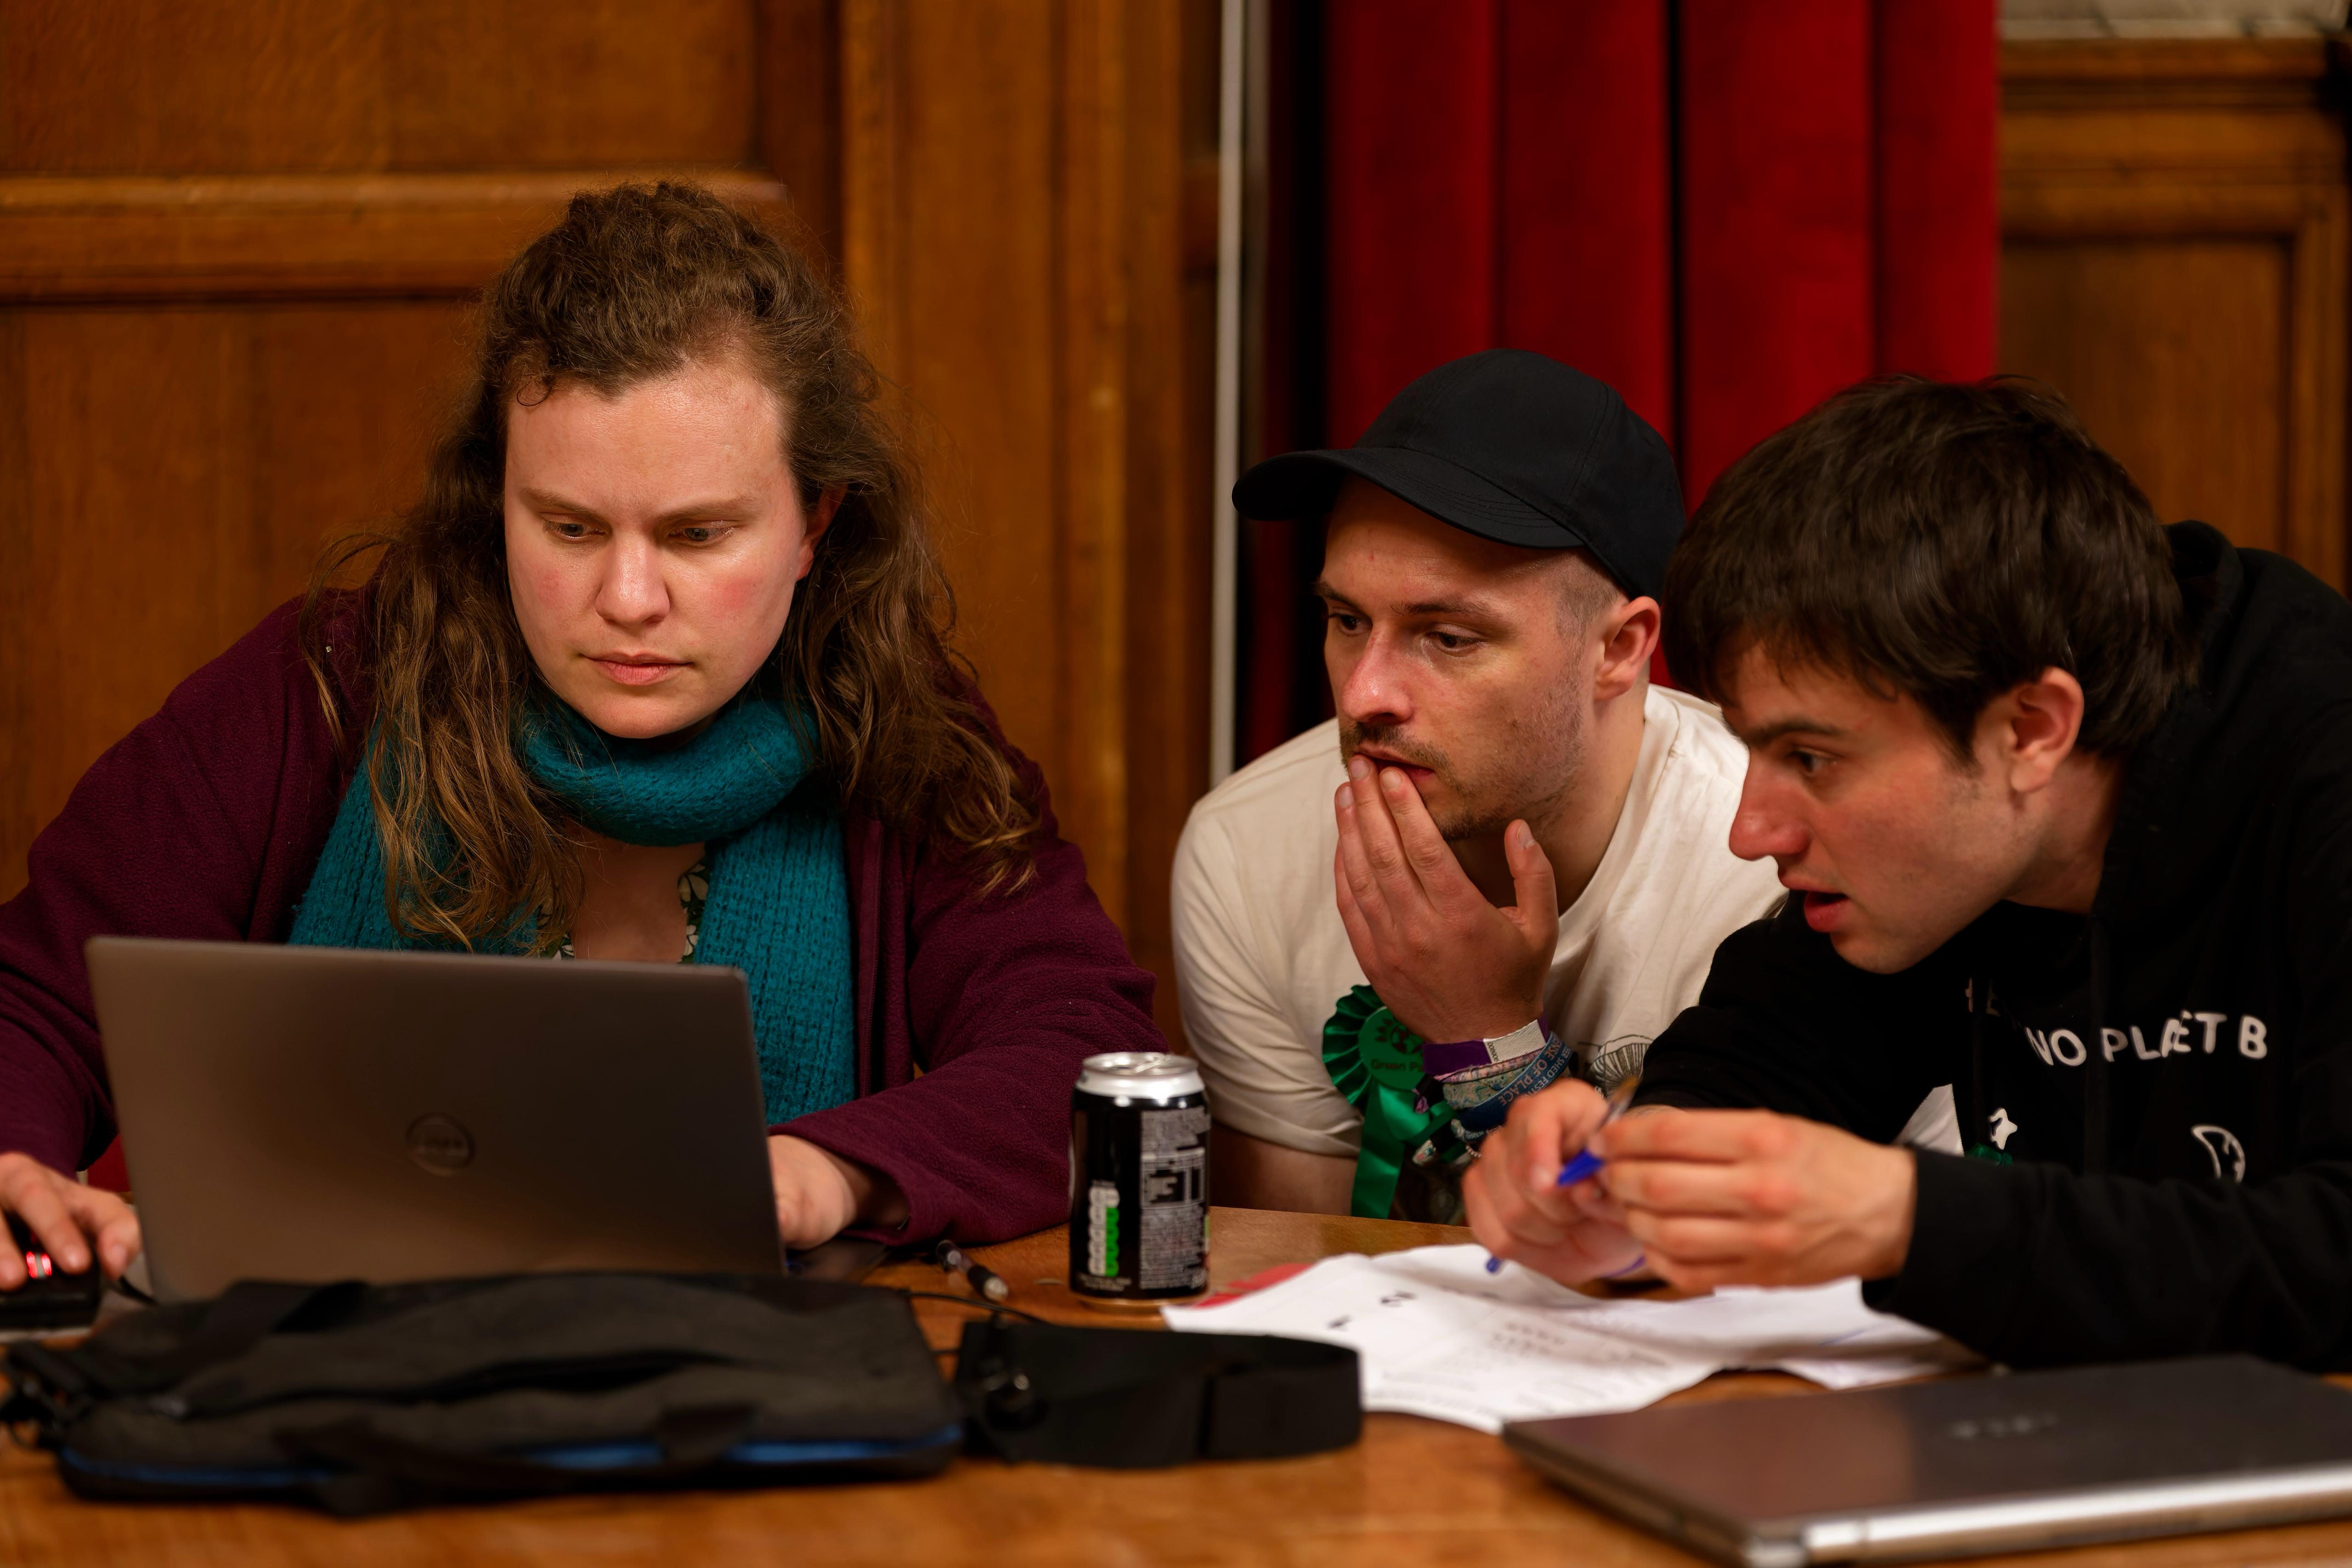 Councillor Emma Garnett, who I worked with on data strategy, during the final vote count.
PauseAI
I was invited by Joseph Miller, founder of PauseAI UK, to give a talk on my work on AI for Good (and also my G7 policy brief on anti-competitive practices in the foundation model market). Though my work on algorithmic governance (i.e. governing by algorithm) would seem to preclude supporting a pause on AI development, I do think that PauseAI is doing a good job of drawing public attention to the harms caused by powerful AI companies. As such, my presentation focused heavily on these issues, specifically on the downstream consequences of market concentration surrounding major AI models and how governments can use existing legislation to reduce monopolistic behaviour.
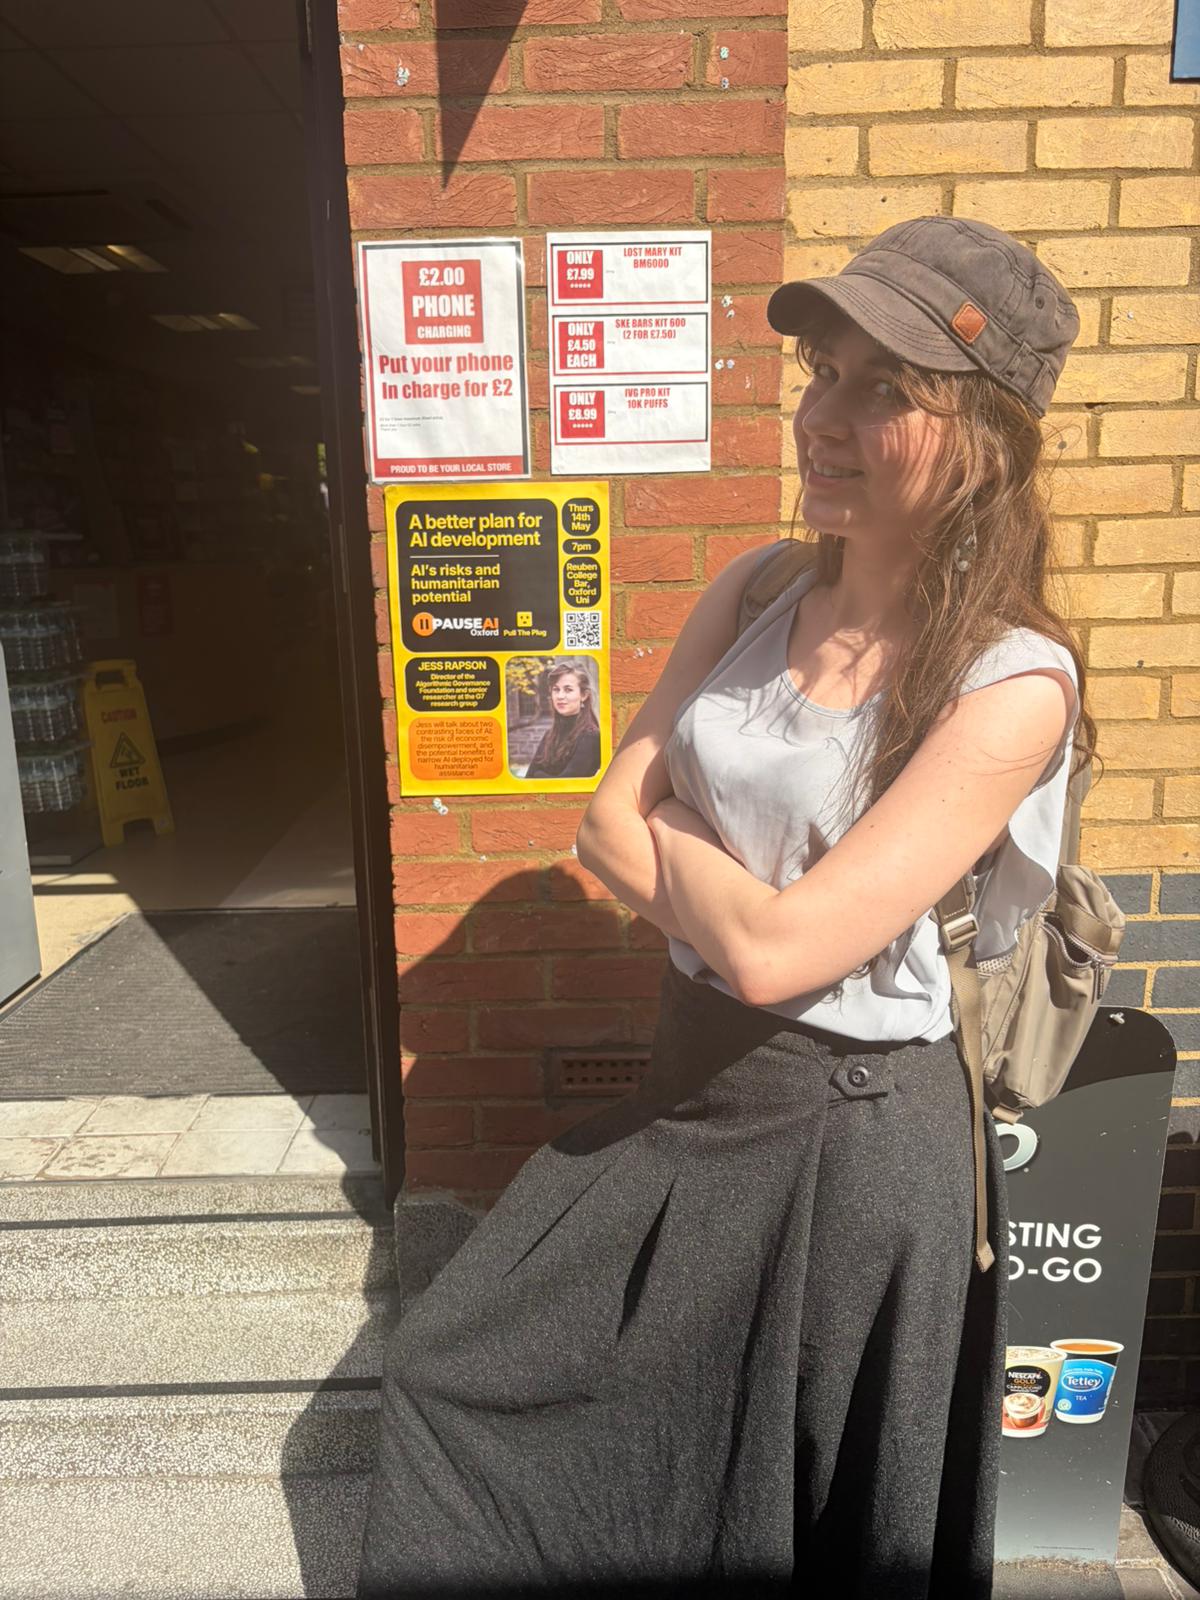 Somewhat surreal to unexpectedly encounter my face at the Oxford bus station.
I am personally quite sceptical that a complete ban on AI development over AI safety concerns would be effective, but perhaps framing their movement around this is a clever door-in-the-face technique that makes it easier to ask for smaller public concessions, like enforcing antitrust law against powerful, vertically integrated megacorporations whose market capitalisations outstrip the GDPs of most countries in the world.
Stats Research
I have also been continuing to plod away at my DPhil research, focusing on developing novel machine learning models with high skill in predicting spatio-temporal extremes. The first component of this project involves developing methods to probe models for structural failures when predicting extreme out-of-sample events. For example, a flood model trained on average rainfall conditions might fail to extrapolate and predict extreme flooding if given extreme rainfall data beyond the range it was exposed to in its training set. I show that pretrained models can be probed to expose this kind of failure before data from the extreme regime even exists.
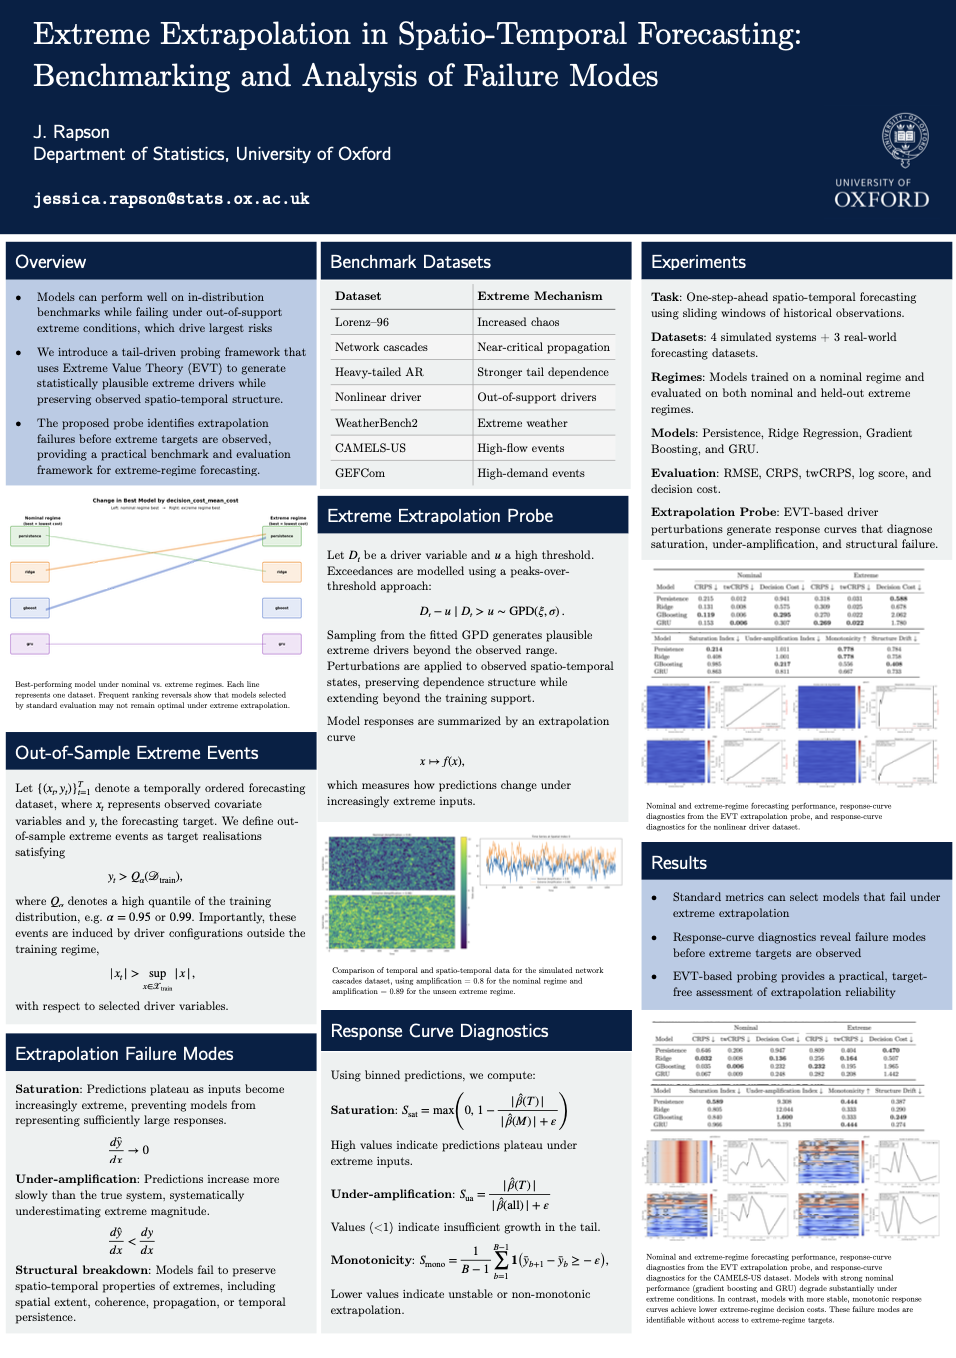 My poster, presented alongside those of other first-year DPhil students.
I’m also tutoring a student over Trinity Term as part of WEPO. The Oxford tutoring system uniquely assigns only one tutor per student, so the lessons are extremely bespoke and in-depth compared to tutorials directed at groups of students. Preparing for these is so much more challenging, as you can’t just go over a general lesson plan; you have to be prepared for the student to request an entire hour deep-diving into one particularly challenging concept or problem. It’s quite stressful to prepare for and almost feels like some kind of oral exam. This is compounded by the fact that the students are quite smart, so the questions they ask are not exactly entry-level.
Vienna
I was invited to attend a workshop run by RiskKAN on AI for Complex Climate Risk Mitigation as part of EGU26 in Vienna. While the workshop was useful for networking, my genuine thoughts on the conference were that I should have submitted something, literally anything, because I’m very confident it would have been accepted. I was honestly a little disappointed by the quality of presentations that I saw.
Maybe this is my bias from stats projects generally focusing on methodology, but almost everything that I saw was a fairly standard data analysis or prediction model applied fairly unimaginatively to geoscience data. A large portion of the presented work also seemed to have serious methodological problems, like data leakage (e.g. evaluating forecasts using a random sample of the data instead of a time-blocked holdout test set) or using evaluation metrics that are mean-biased and don’t assess performance at the extremes (even though incorrect extreme predictions carry much higher costs in the domains where these metrics are used). Honestly, the way that people in these fields were (not) thinking about extreme forecasting was quite inspiring for my DPhil work.
That being said, I did find some interesting things:
| Paper / project | Authors | Key points | Relevance |
|---|---|---|---|
| XFires: Gaining a holistic understanding of extreme fires and their impact in the Earth system using satellite data records generated by the ESA Climate Change Initiative | Sitch et al. | A 0.25° global grid in NetCDF format tracking extreme and normal fires at sub-monthly and monthly resolution. Website | A useful dataset, once published, that I could use in my research and applied work. |
| Beyond In-Distribution Skill: Towards Robust ML Parameterisations for Non-Stationary Climate Systems | Stanley-Clamp et al. | Uses the theory of compositional generalisation to build machine-learning models that are less susceptible to shifts in distribution. | Someone I should probably reach out to at Oxford about potential collaboration. |
| AI-generated ensemble river flow forecasting: Using rollout and an additional noise input to build ensemble forecasts | Karan Ruparel et al. | Develops an actual new method for enforcing temporal consistency in multi-lead machine-learning forecasts. | Not that related to my research, but new methodology for producing coherent ensemble forecasts across multiple lead times, which is quite useful and interesting. |
And Vienna was great.
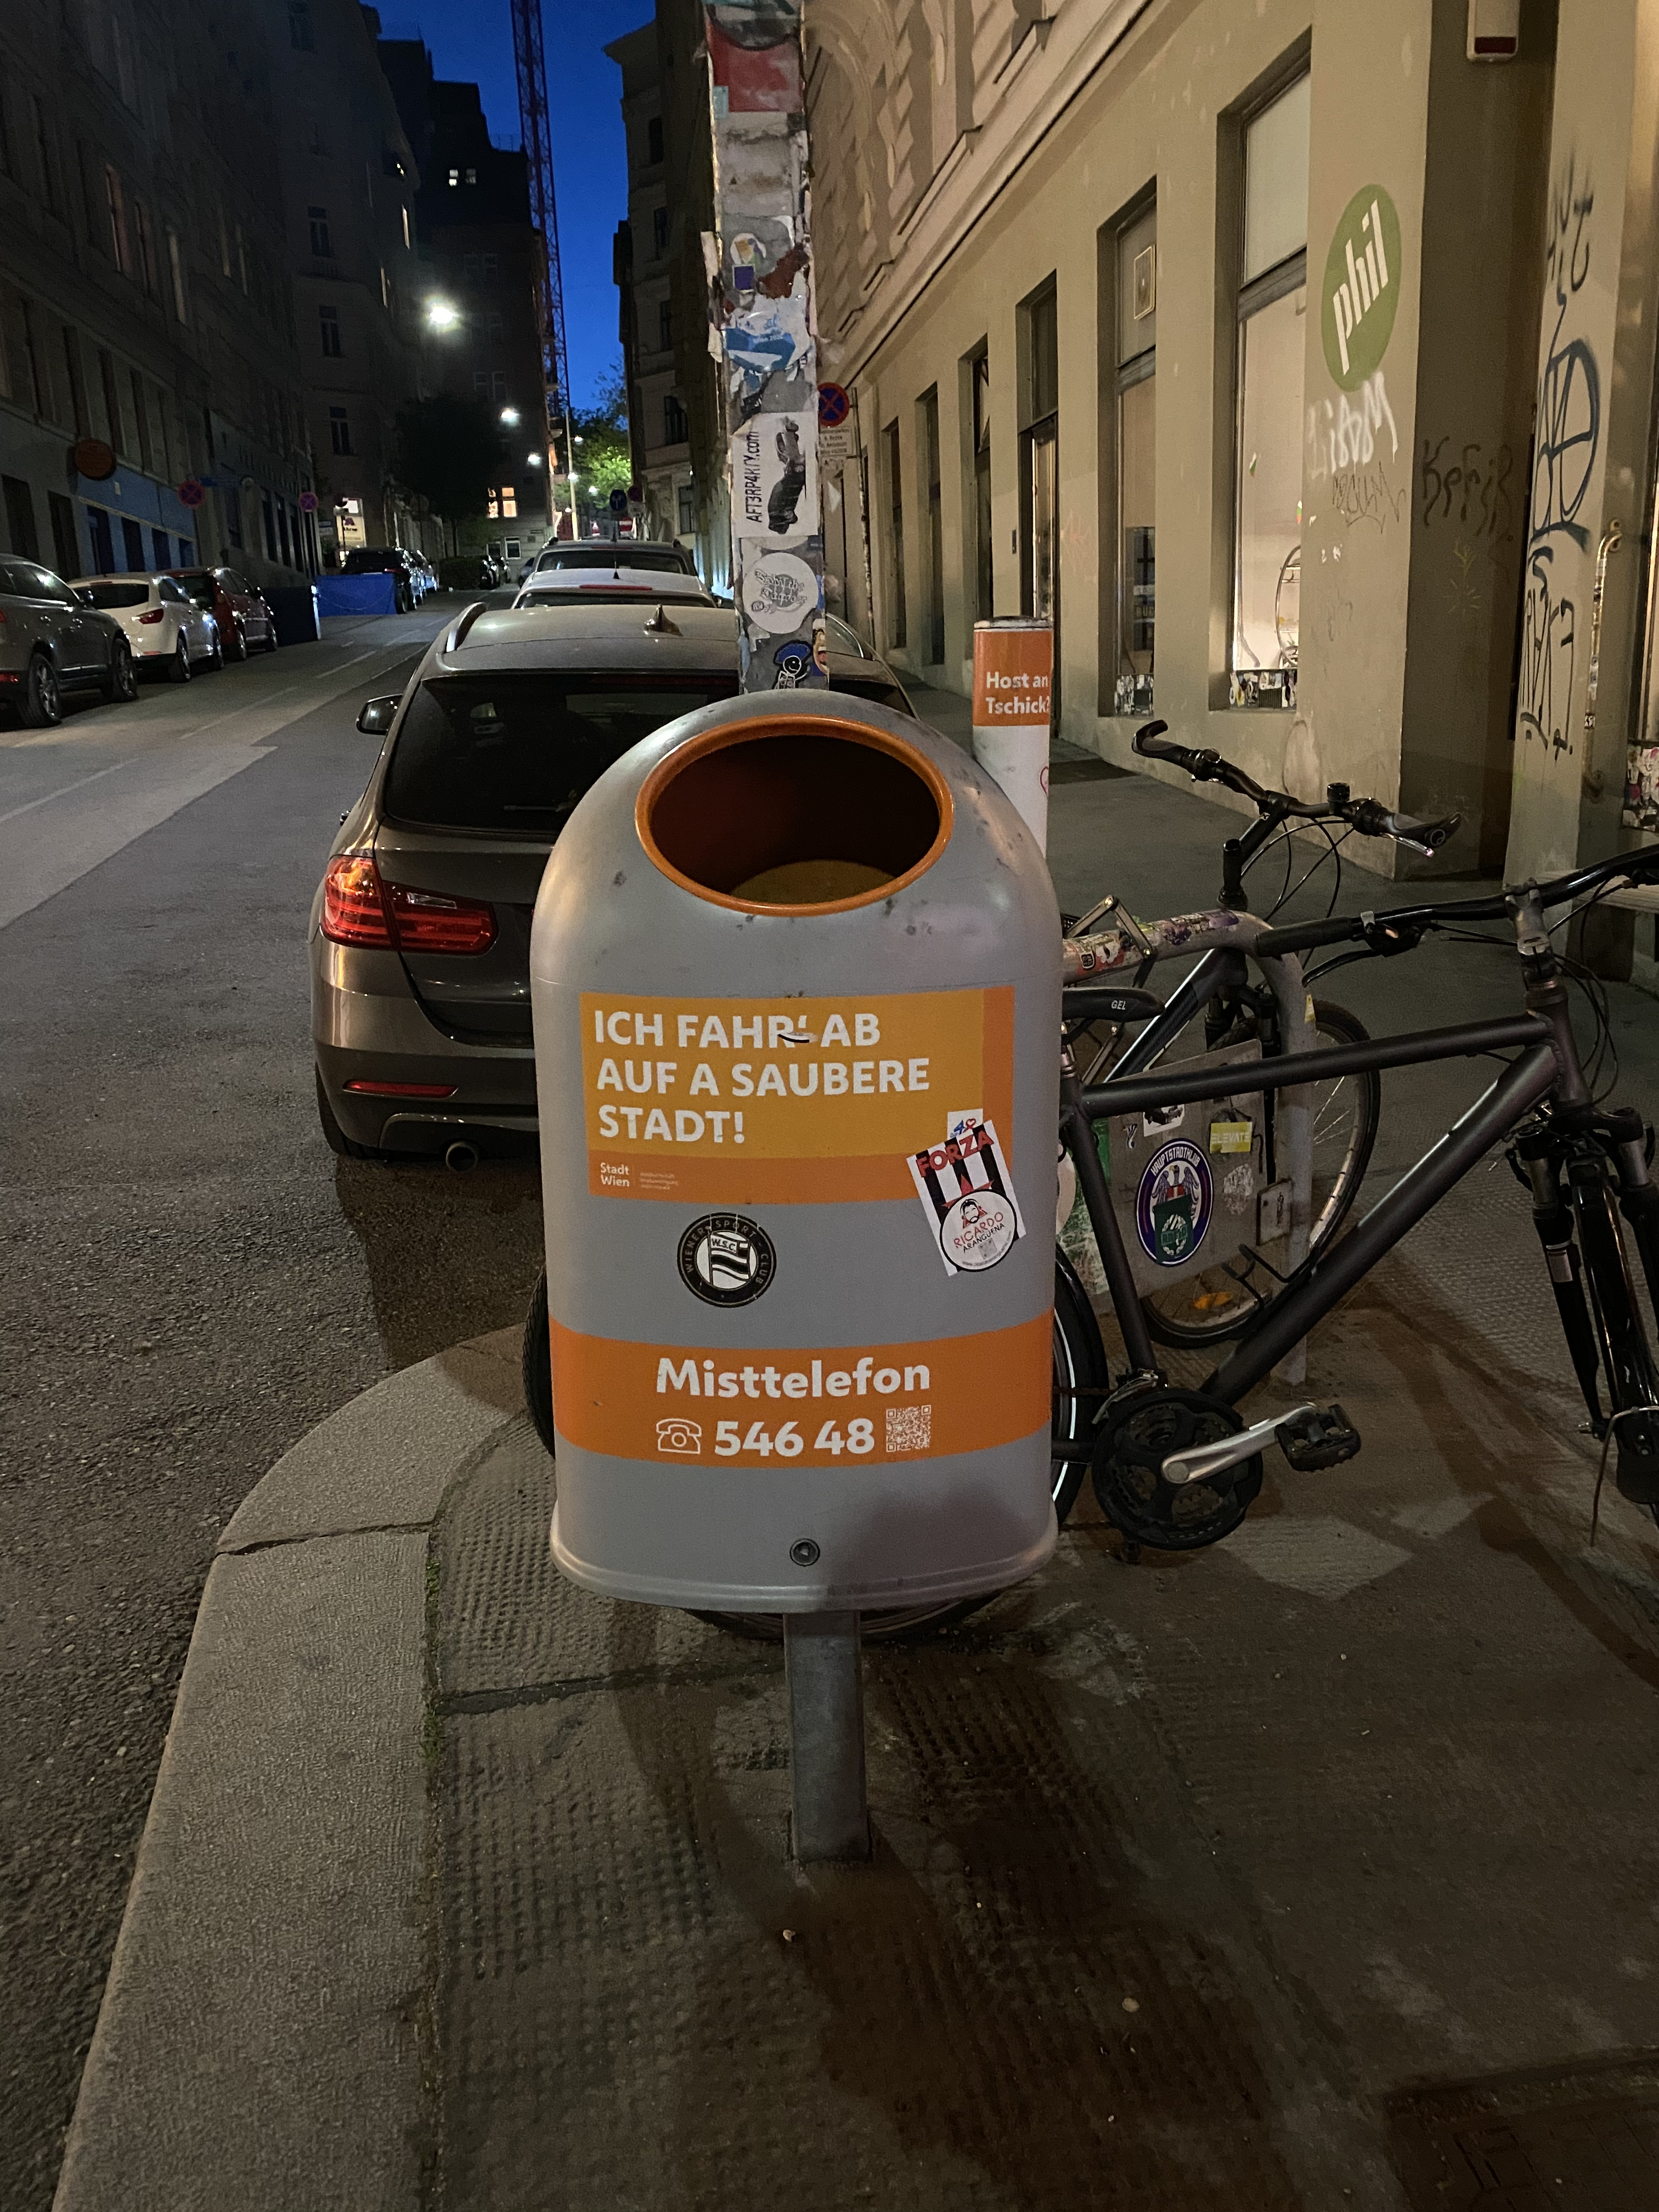 All the bins are puns. For this one, “abfahren auf” can mean “to drive to” or “to be really into (something)”, so its meaning is both “I’m driving to a clean city” and “I’m really into a clean city.”
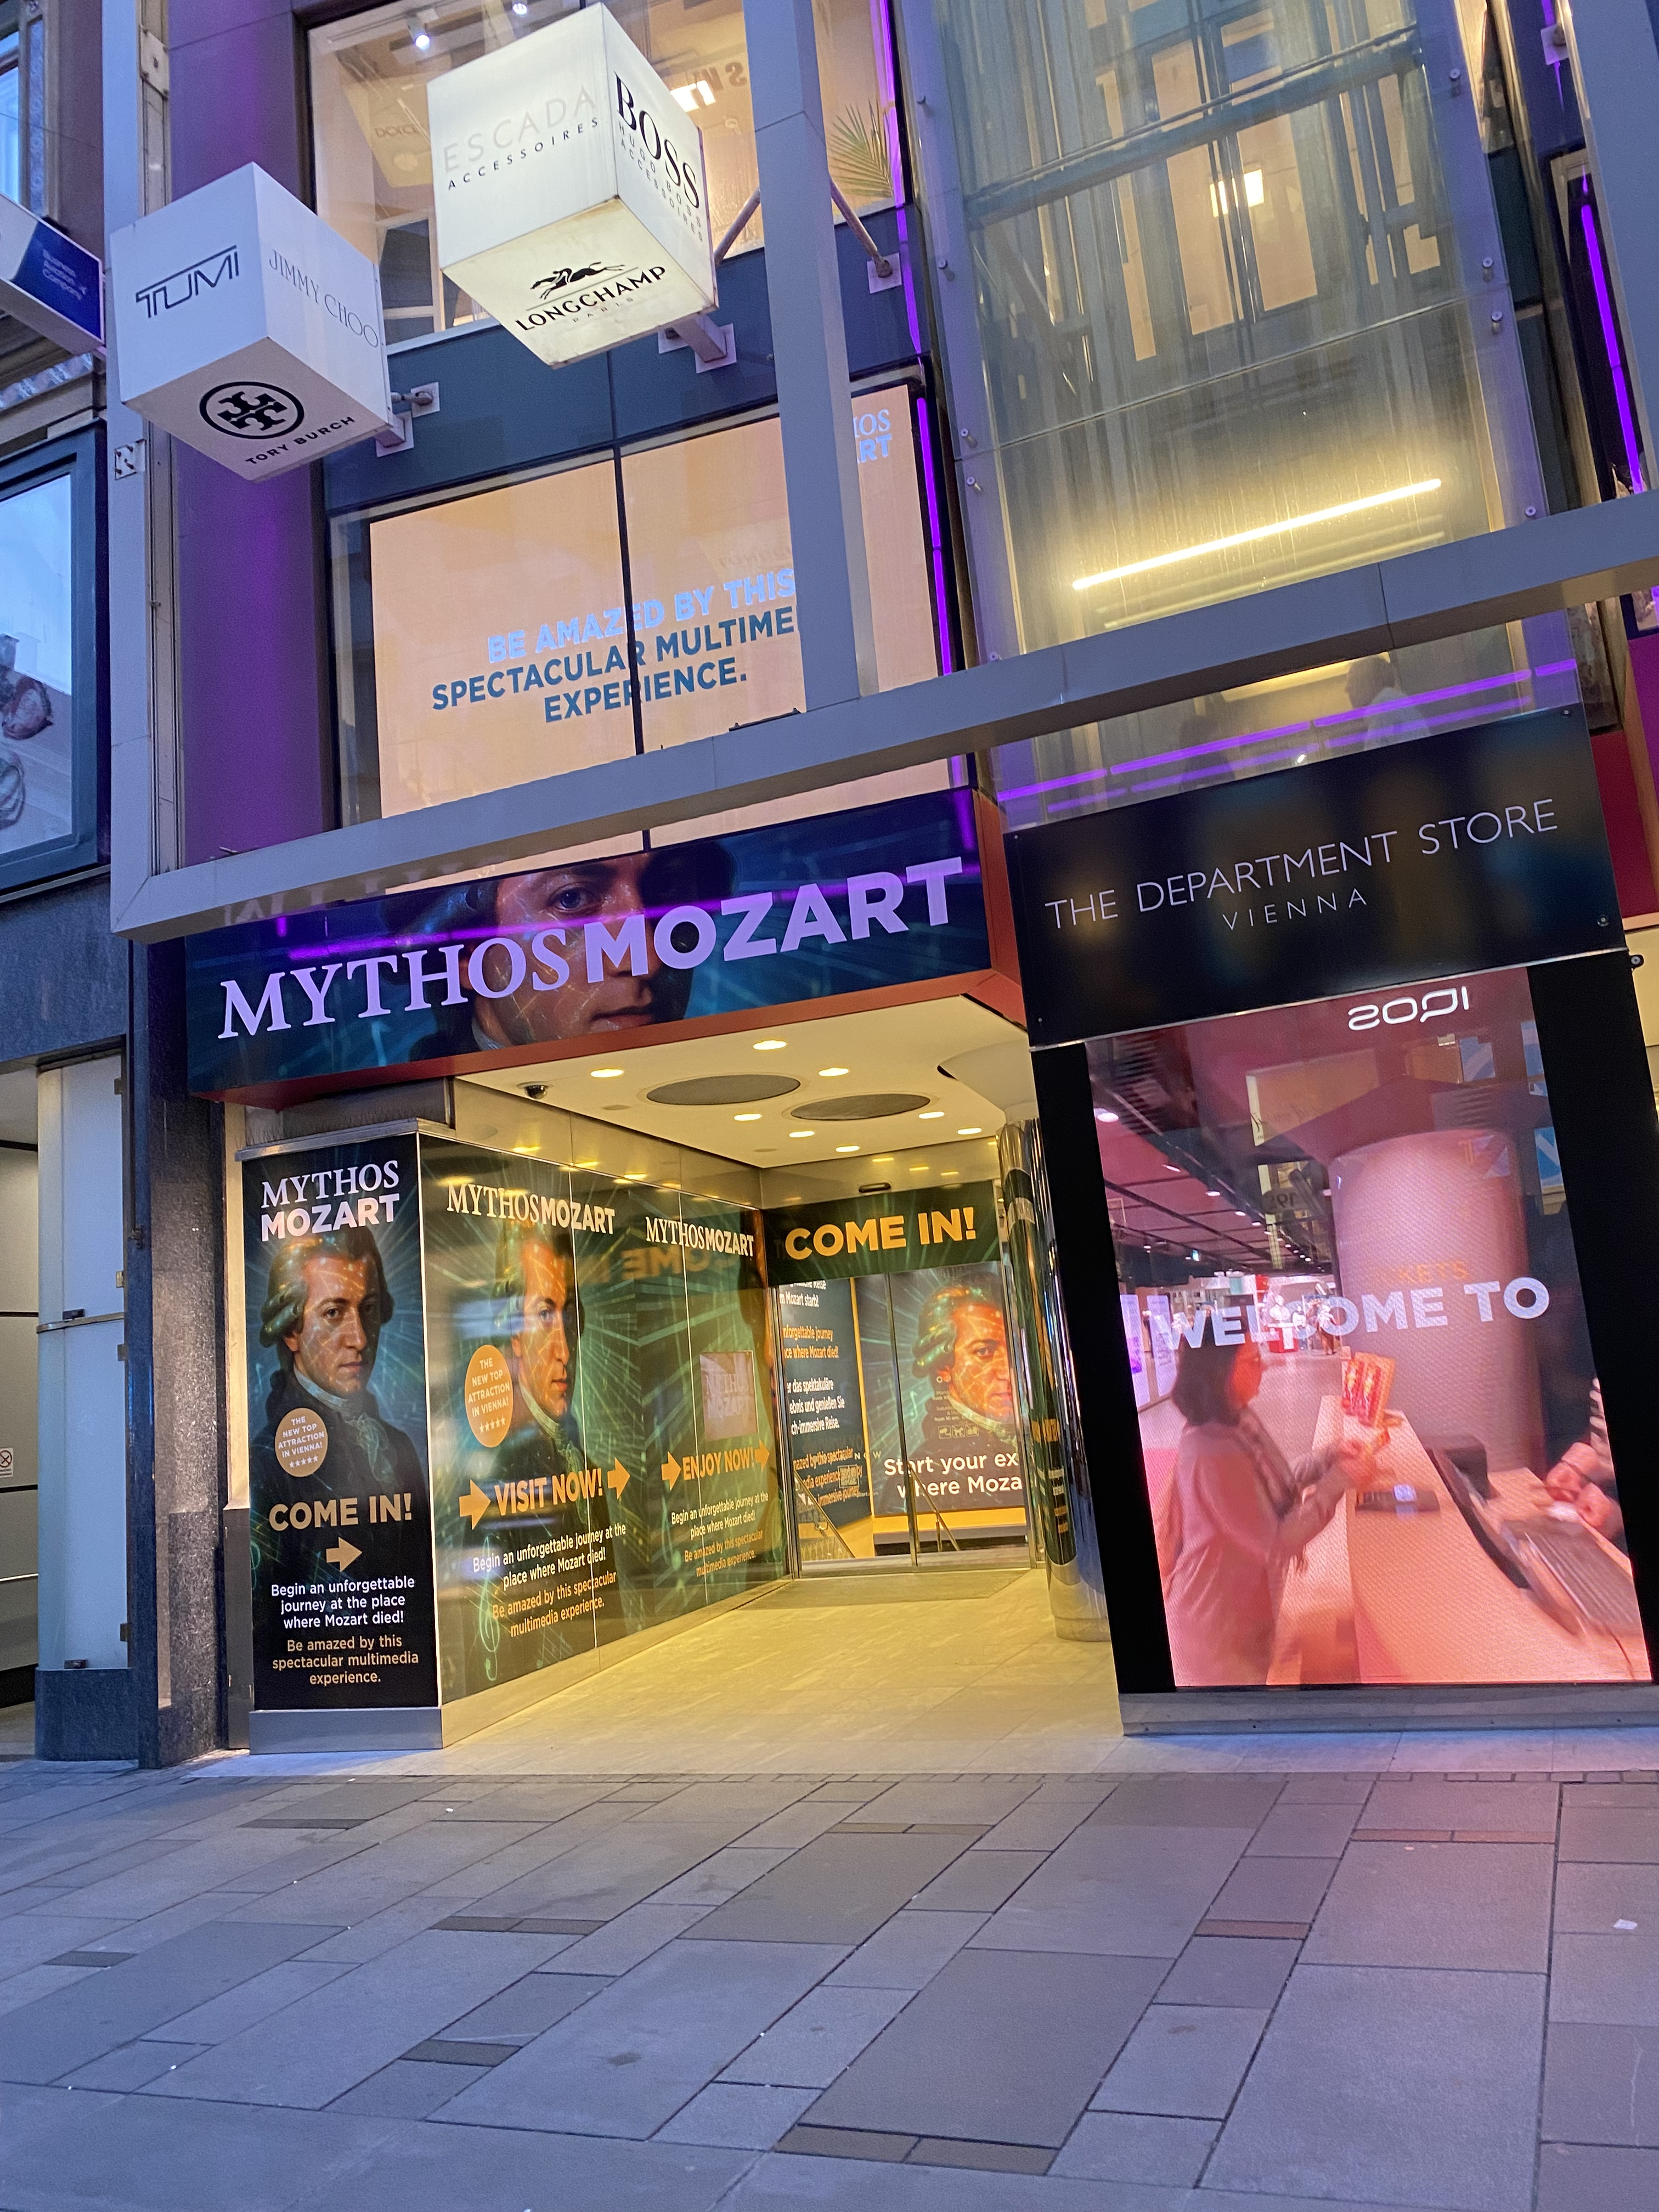 A tasteful, spectacular multimedia experience in the place where Mozart died.
 Good city for the addiction.
London
I was also in London for EA Global. It was my first one and also my first time using Swapcard, which is by far the superior way to do conferences. Basically, everyone inputs their information, what they are hoping to get out of the conference, and the types of people they would like to meet. Then all attendees can download the data as a CSV and filter profiles to arrange 30-minute meetings. This kept me extremely busy over the three-day conference, with back-to-back meetings all day, but it was definitely more productive than EGU26, where I had to wander around and hope that some of the random conversations I struck up might be useful. I probably missed tons of people who would have been really good to speak with.
 The Greenwich foot tunnel, which we had to take after all the trains from Greenwich Peninsula (where the conference was held) randomly stopped running when we left the venue late. Fun fact: it takes three hours to leave Canary Wharf on foot.
The Failure of the War on Iran: An Image
I also messed around a bit with some public data to make a quick visualisation regarding the war in Iran (methods, data, and code here).
 I really like adding events to time-series plots like this because it helps to tell a story. Here, you can instantly see the efficacy of the JCPOA and the absolute failure of Trump’s post-JCPOA military actions to contain the intensity of Iranian uranium enrichment.
Where the Wind Blows
Considering the failure of last month’s diving trip, I also spent a bit of time building a quick tool to produce accurate wind forecasts, temporally aligned to the dive plan.
One of the problems I noticed prior to the April diving trip was an overreliance on point wind forecasts, which don’t actually show the range of uncertainty associated with the forecasts. To address this, I built a custom forecast app on my phone that is plugged directly into the NOAA GEFS ensemble wind forecasts. These have skill up to 10 days in advance, with well-calibrated uncertainty ranges that become increasingly narrow the closer you get to the forecast date.
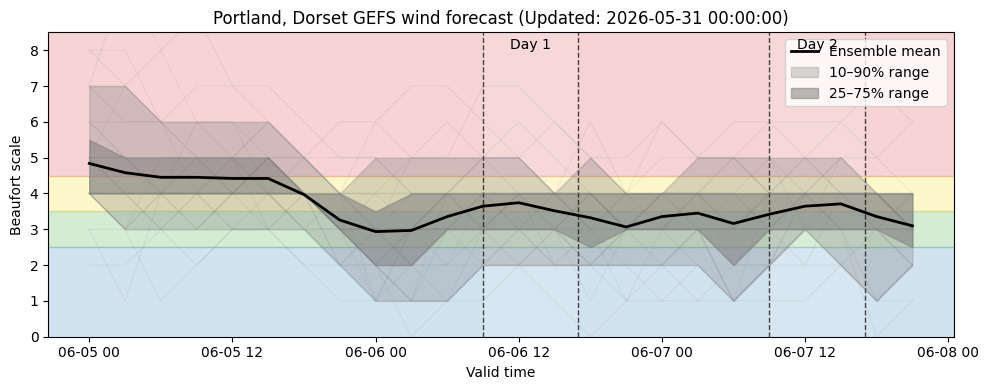 It’s even aligned to the Beaufort Scale, which people here seem to use instead of knots, with colours indicating the feasibility of diving.
With more accurate uncertainty and higher forecast lead time, I probably would have chosen to join the trip later in the week rather than on the weekend, when the wind conditions made diving impossible. I hope to use this in the future to plan better.
Other Life (and Others’ Lives)
Kicked off the month with a renters’ rights party on Labour Day to celebrate the *Renters’ Rights Act 2025* coming into effect at midnight.
 Drew another charcoal picture of Alec, which I think is a marked improvement.
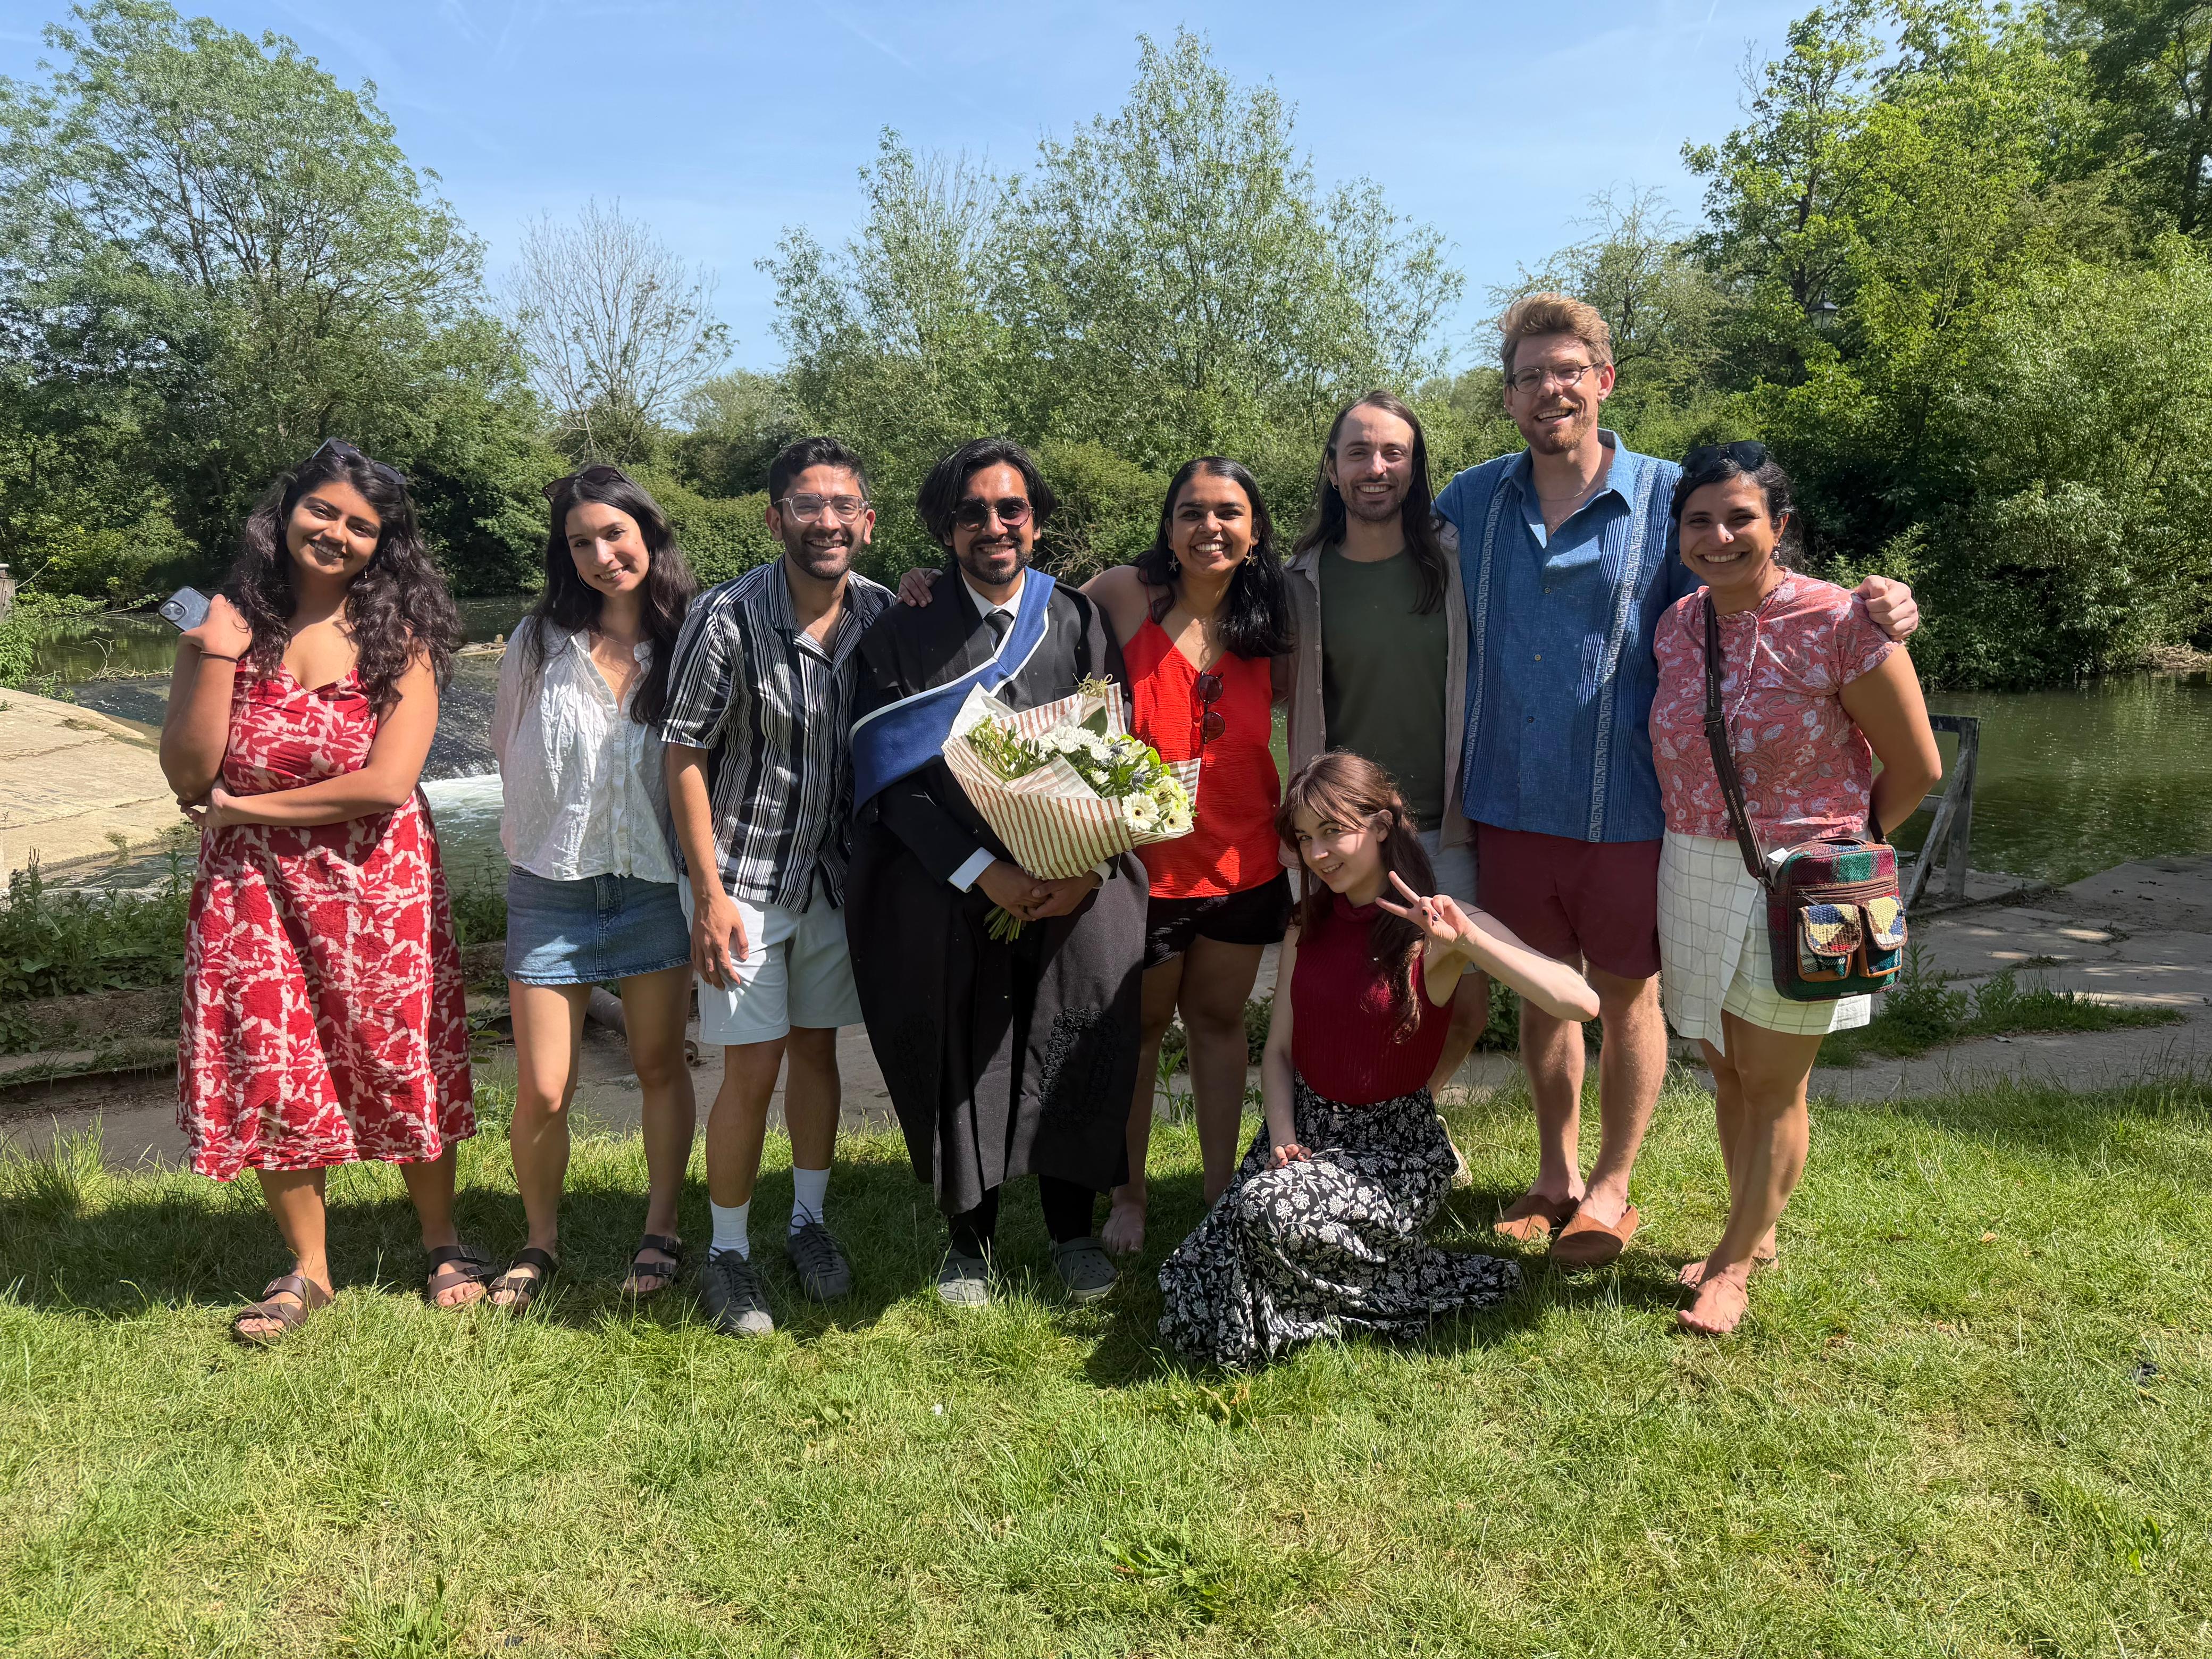 Celebrated my friend’s graduation.
Thoughts on Aging
I have aged again. This time, for the last time in my 20s. It is incredibly strange to think of myself as “almost 30”. On top of the mental hurdle of needing to stop thinking of myself as young very soon, I think I am very driven by a fear of not having enough time to do the things I want to do with my life, and ageing feels like a ticking clock telling me I have one fewer year left.
As such, I find birthdays very distressing.
 One year older, time flies.
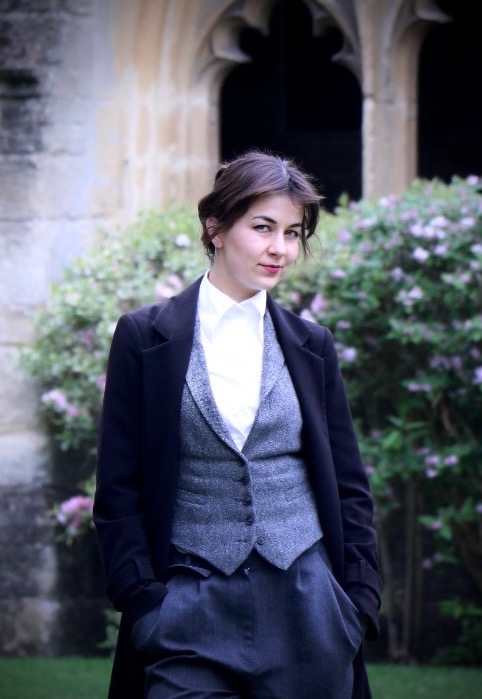
Aaand an updated professional photo I can use everywhere, since my old one (see: the PauseAI poster) is now officially ten years old.
Despite that, I do feel like I have accomplished a lot of what I have set out to do (even though there are so many other things).
Writing about myself does not come naturally to me, but it’s really satisfying to look back at all these posts since I started writing monthly updates two years ago and see what I’ve done and what I was thinking at the time.
Thanks to all the tens of people who read these!